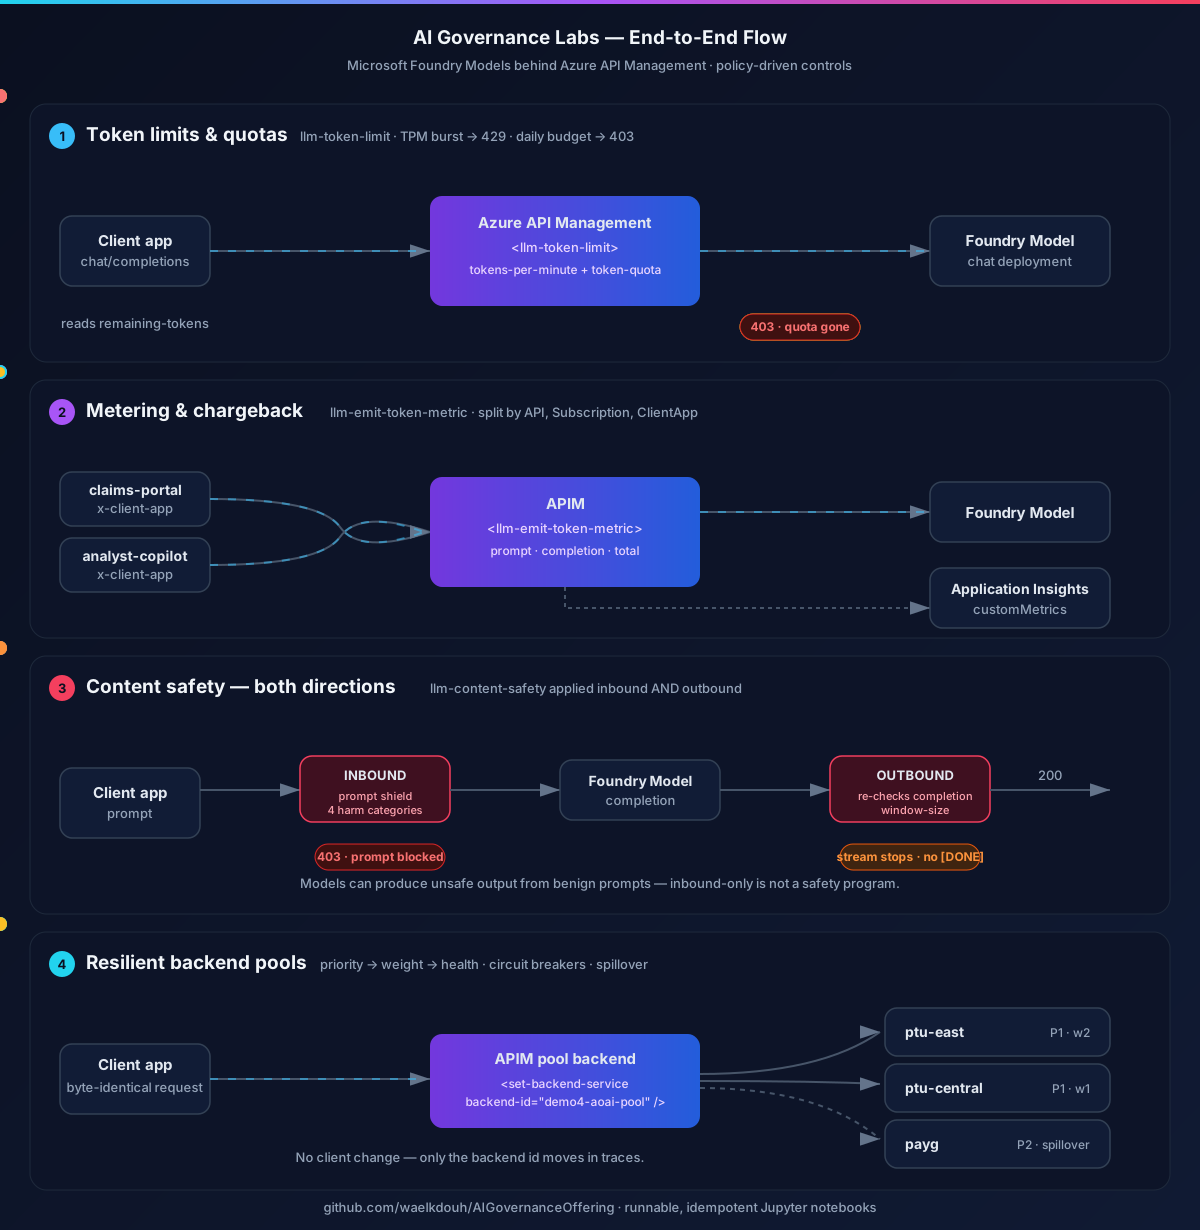
Welcome to AI Governance Labs, a bilingual, hands-on series that governs Microsoft Foundry models behind Azure API Management (APIM) with gateway policy instead of application code. You will apply token limits and quotas, emit token metrics, inspect content in both directions, route through a resilient backend pool, produce an estimated model-token showback, and tear down the resources a session created.
[!IMPORTANT] Use synthetic prompts only. LLM message logging stays off on every API, so the labs never record prompts or completions in telemetry; only token counts and bounded dimensions leave the gateway. Session images appear on this site only after a maintainer reviews sanitized evidence.
What you will build
One APIM Basic v2 gateway fronts one approved model deployment and an Azure AI Content Safety resource. Workspace-based Application Insights receives token metrics through a managed-identity logger with local authentication disabled. Five Python notebooks configure demonstration APIs on that gateway, and a platform API named ai-gateway-api serves three team products for the showback lab.
What the labs do not prove
Read these limits before you run any lab. Each lab page repeats the limits that apply to it.
- Basic v2 is a conditional choice. Its gateway is a public endpoint with no inbound private endpoint and no private backend connectivity, so the deployment requires explicit approval of public exposure. When private networking is required, choose Standard v2 and validate that topology separately.
- The resilient pool routes to mock members hosted on the same APIM instance. It demonstrates routing decisions, not live multi-region resilience or provisioned-throughput behavior.
- Content safety results can be
inconclusive. An inconclusive required objective prevents any claim that every lab succeeded. - The showback lab produces an estimated model-token showback at uncached retail prices. It is not a billed chargeback, and it excludes shared platform, logging, safety, networking, tax, and contract costs.
- Teardown runs as a dry run by default, reports residual exposure, and never purges. Purging soft-deleted resources is a human-only operation.
Learner paths
You can follow the labs in two ways. The interactive path runs each notebook yourself against an APIM instance you already own, starting with an az login session. The automated path runs a protected, manually approved GitHub Actions session that deploys the environment, runs the five notebooks headlessly, generates bounded traffic, reports estimated showback, and cleans up the resources it created.
Neither path requires GitHub Copilot or any other AI coding assistant. AI-assisted tooling helped draft these pages, and maintainers review every page before publication.
Labs
The full curriculum lives in Labs.